
Do we need separate Video Encoders like VJEPA? Can we use pretrained image encoders like dinov2 (with minimal adaptation) for understanding video? Can we train image encoders with video objectives and
in between the backbone layers
- trainable adapters
- Multi-View Foundation Models (technically not video, but related)
- Exploring Temporally-Aware Features for Point Tracking
- attention over memory (qk)
after the backbone layers
- Advancing Video Self-Supervised Learning via Image Foundation Models
- Recurrent Video Masked Autoencoders
some evidence of plausibility
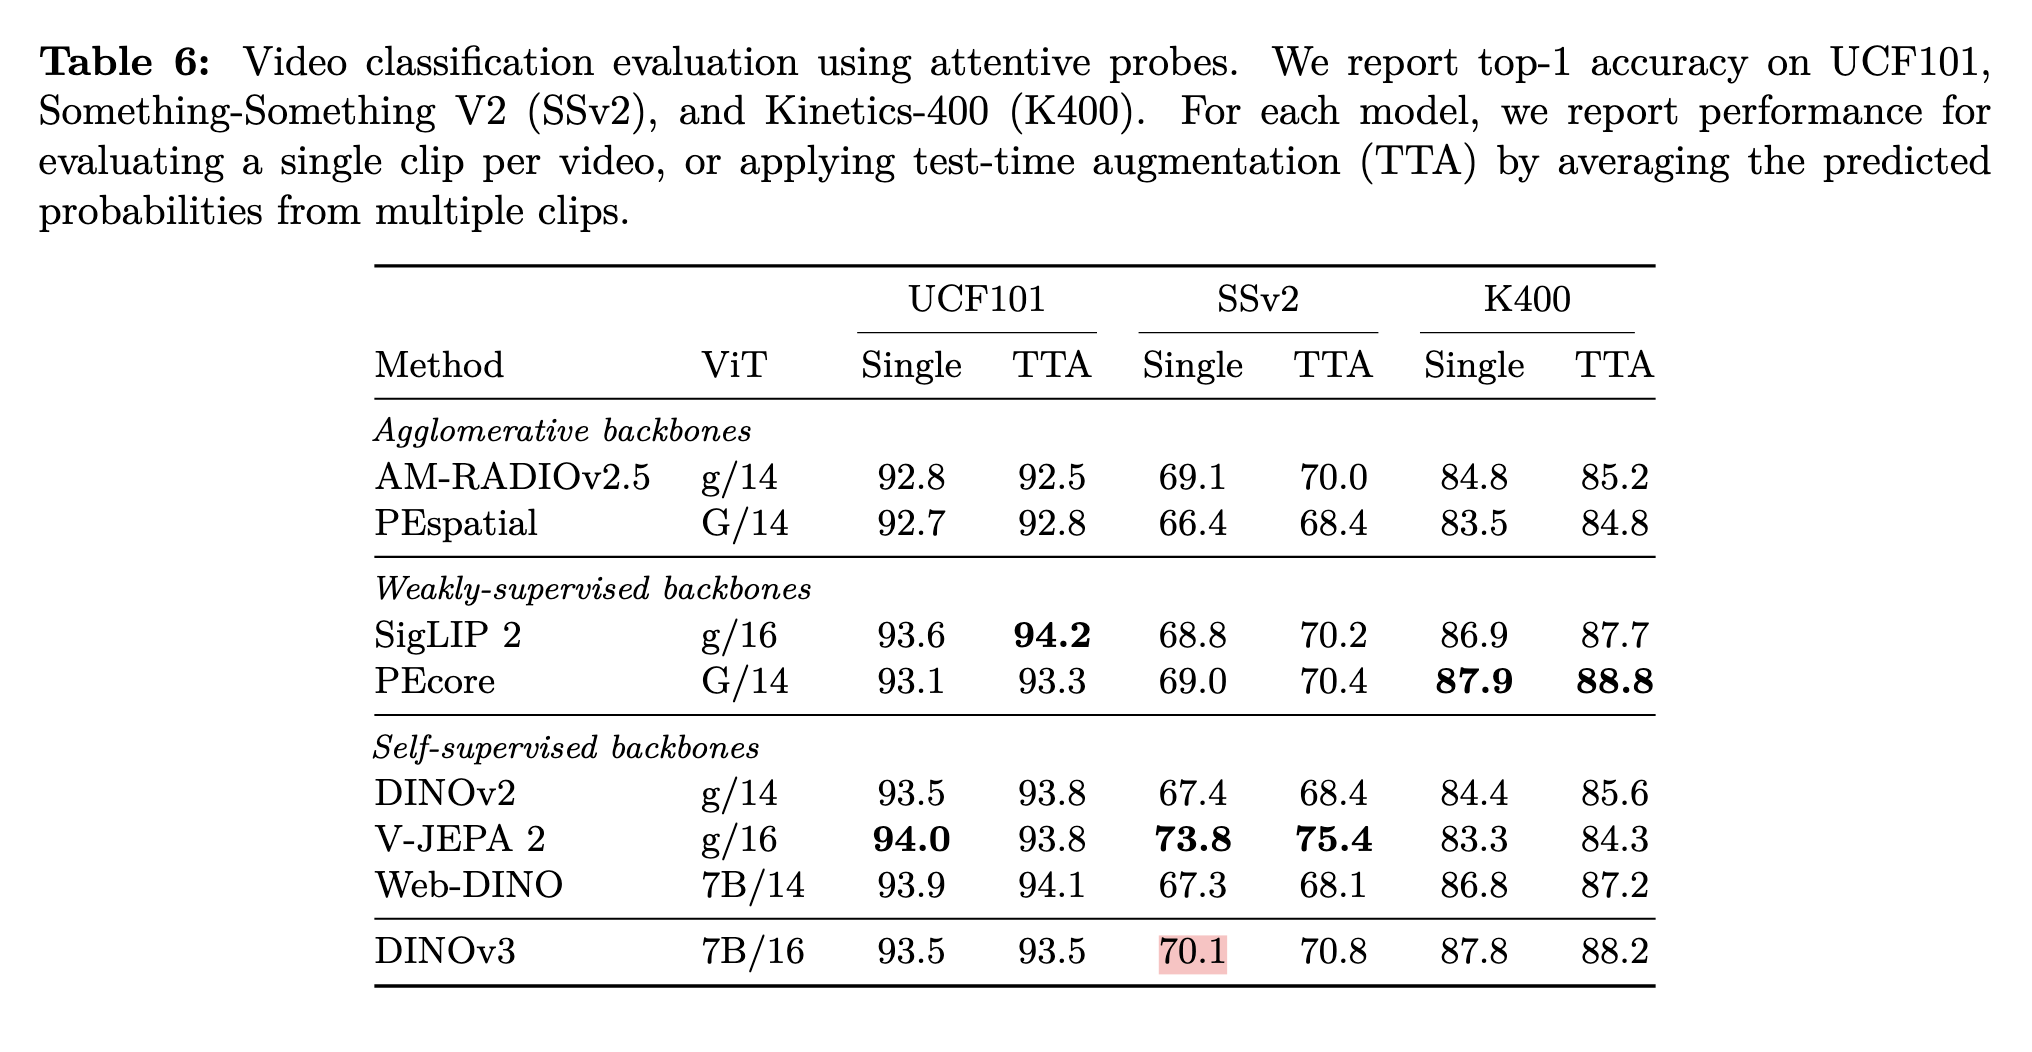
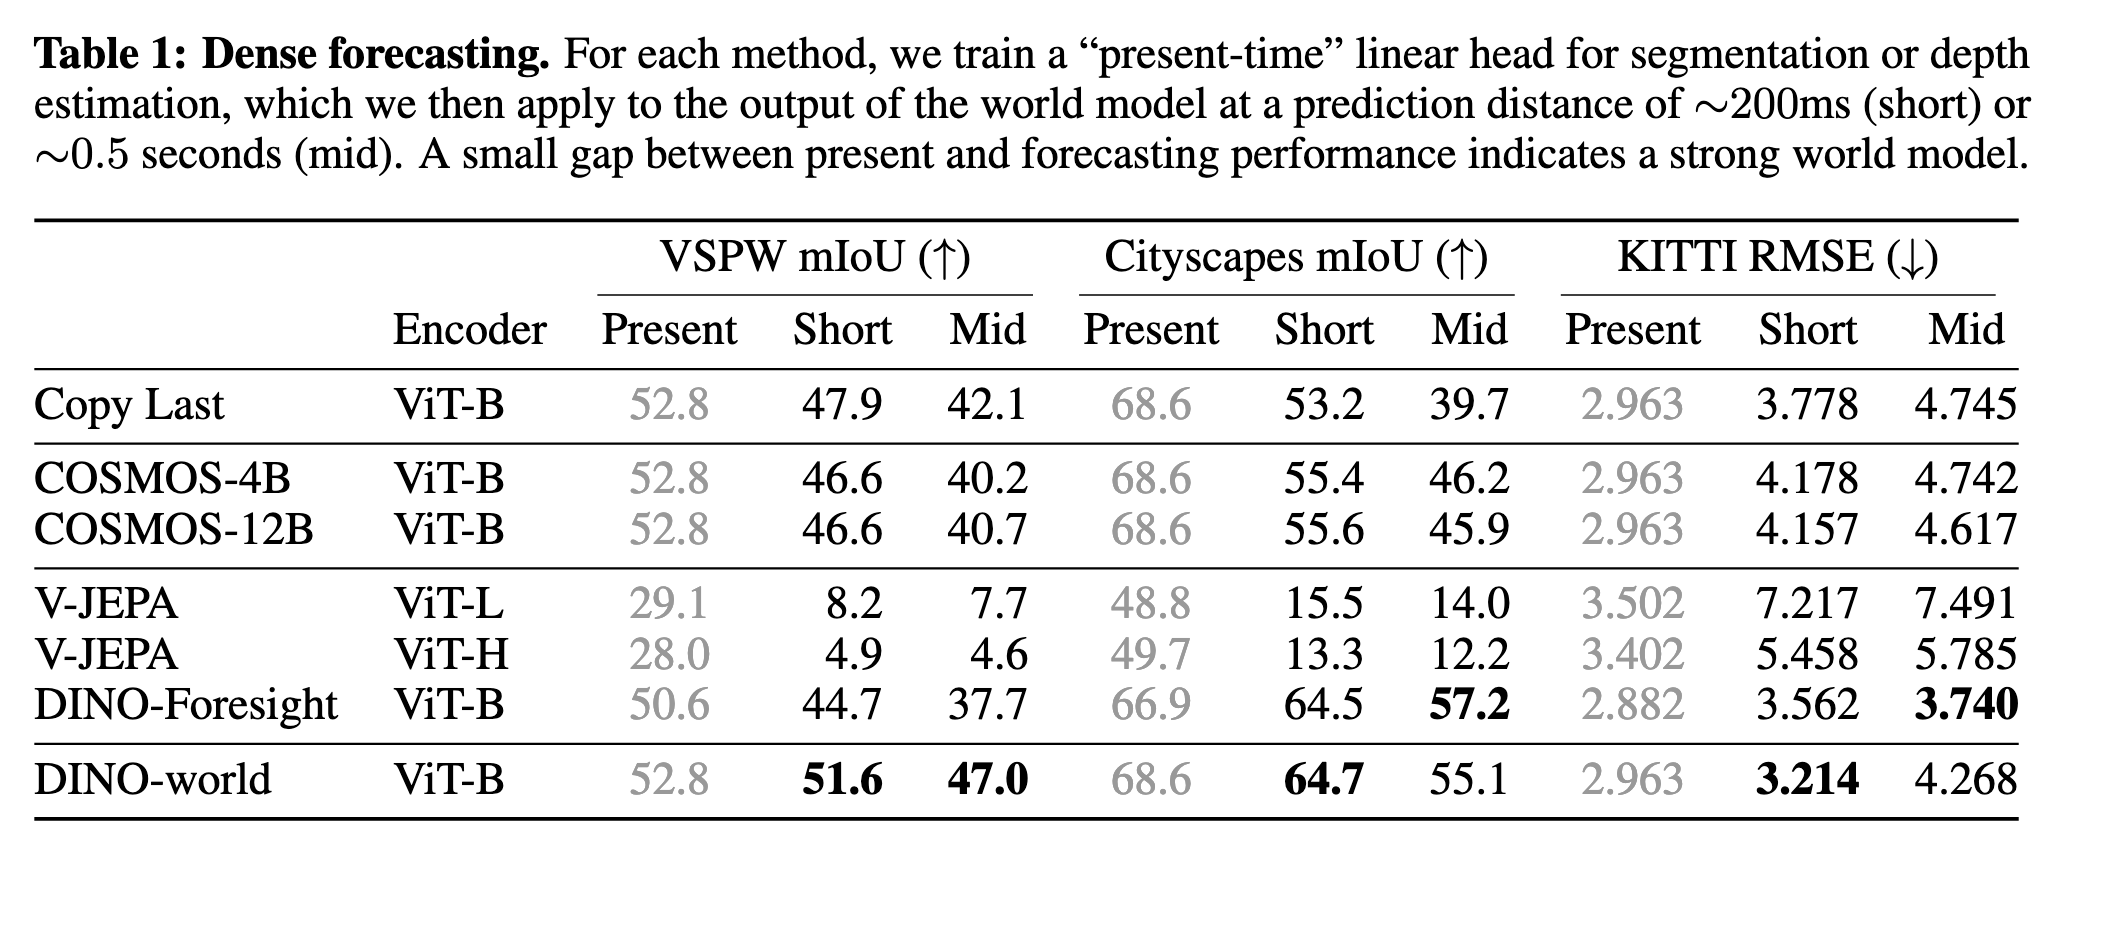
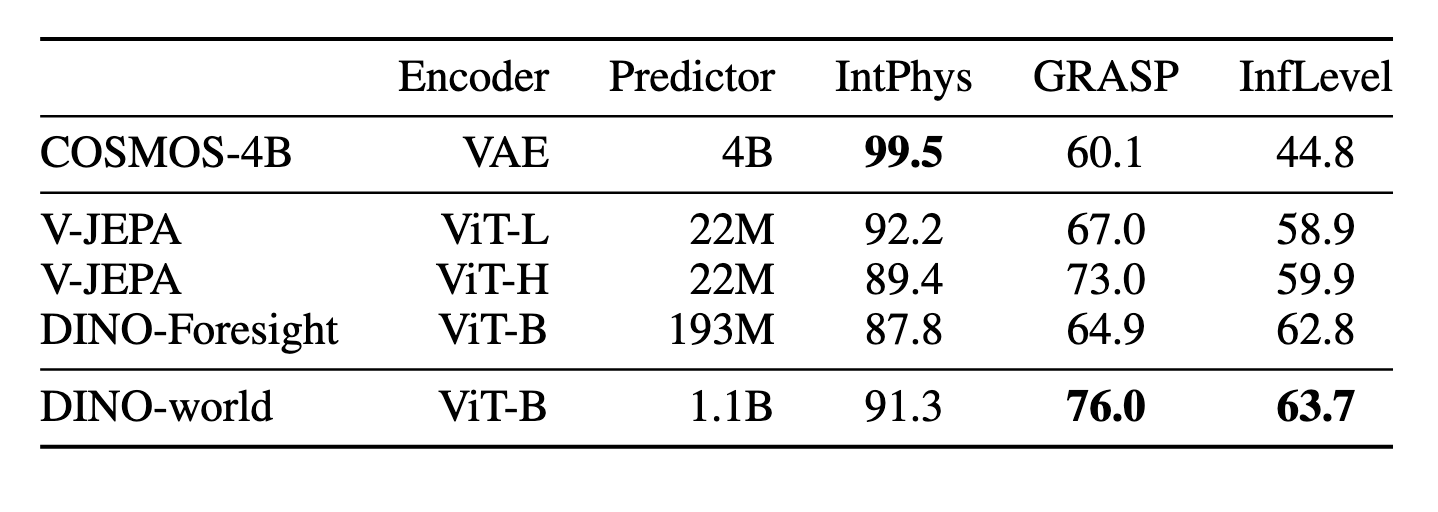
DINOv2/DINOv3 features does incredibly well on video tasks (video classification, dense forecasting, intuitive physics).
From DINOv3.
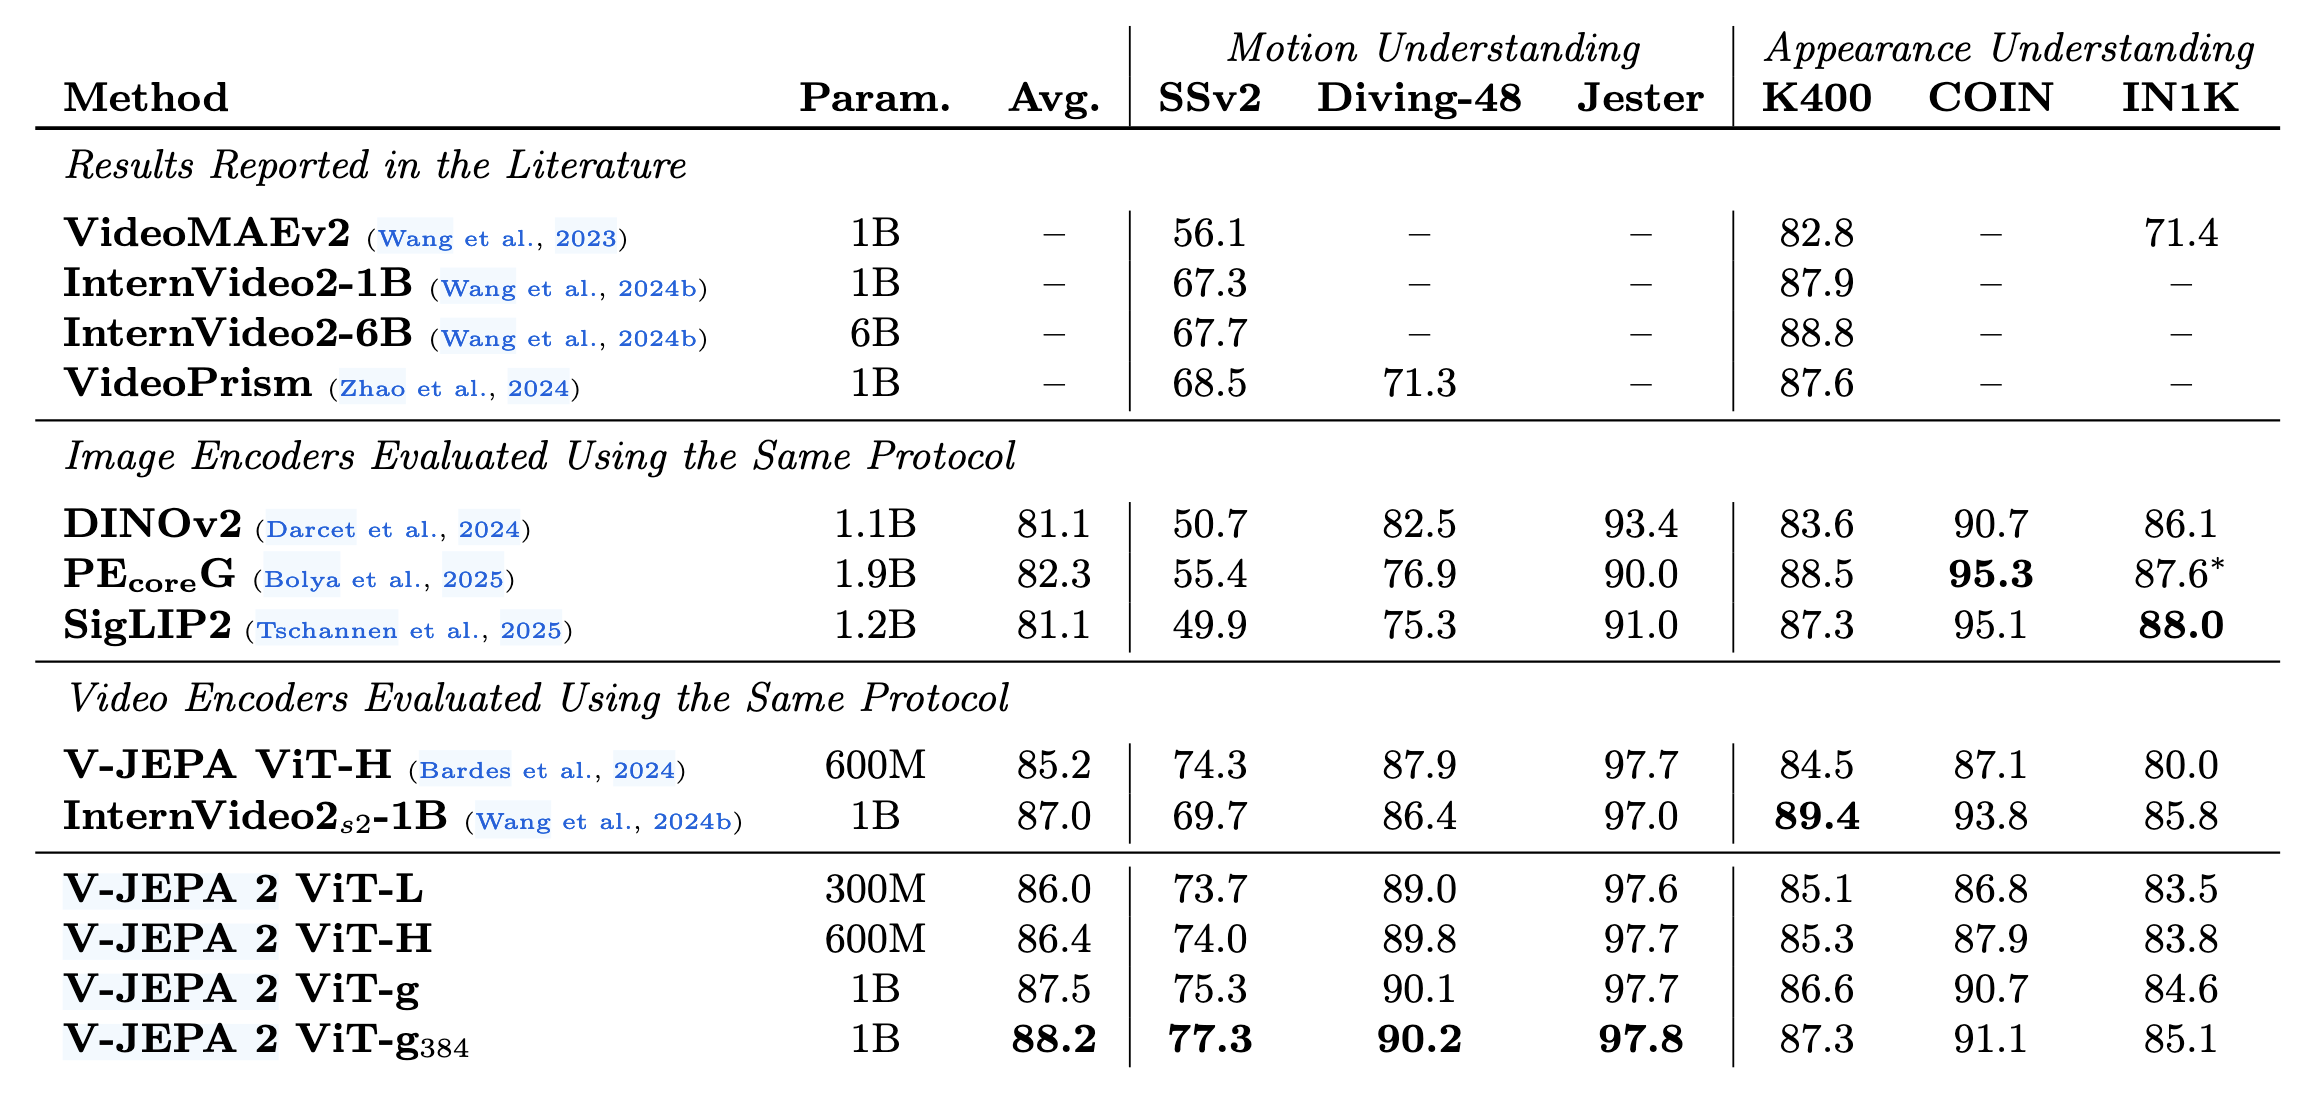
Small caveat here, in the V-JEPA 2 paper they report
From Back to the Features - DINO as a Foundation for Video World Models
PEcore also does incredibly well, and their video adaptation is very simple: from (video, label) pairs, they average the last-layer features and train it contrastively.